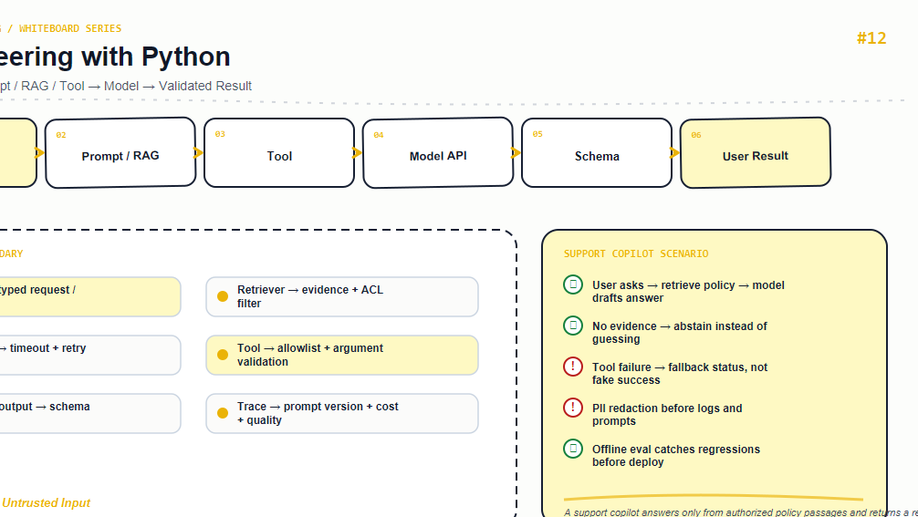
AI Engineering with Python
A scenario-driven guide to AI Engineering with Python, including boundaries, failure paths, and production trade-offs.
Python
AI Engineering
3 min read
Thoughts on AI engineering, RAG, and LLM applications.
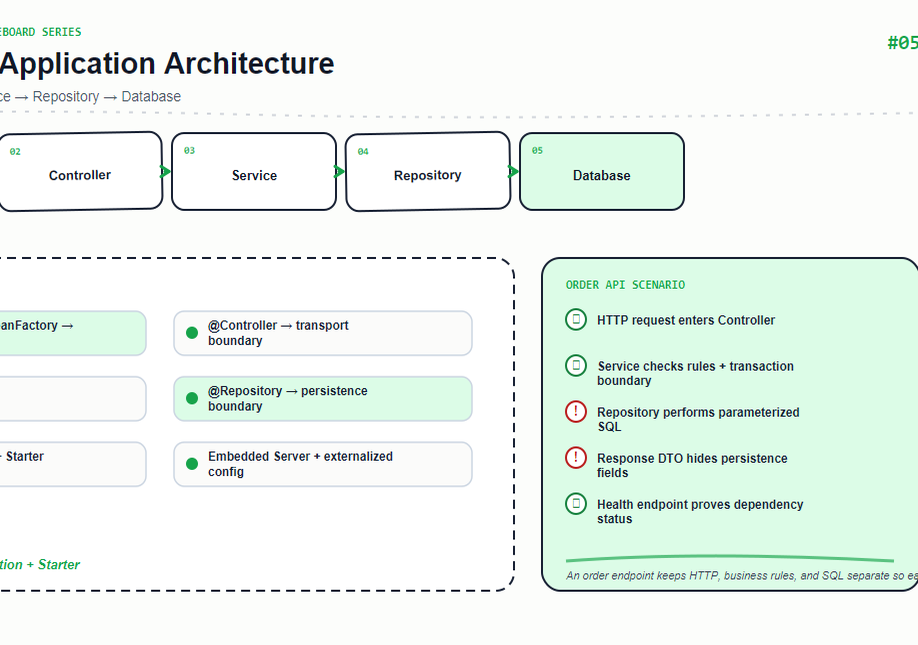
A scenario-driven guide to Spring Boot Application Architecture, including boundaries, failure paths, and production trade-offs.
A scenario-driven guide to AI Engineering with Python, including boundaries, failure paths, and production trade-offs.
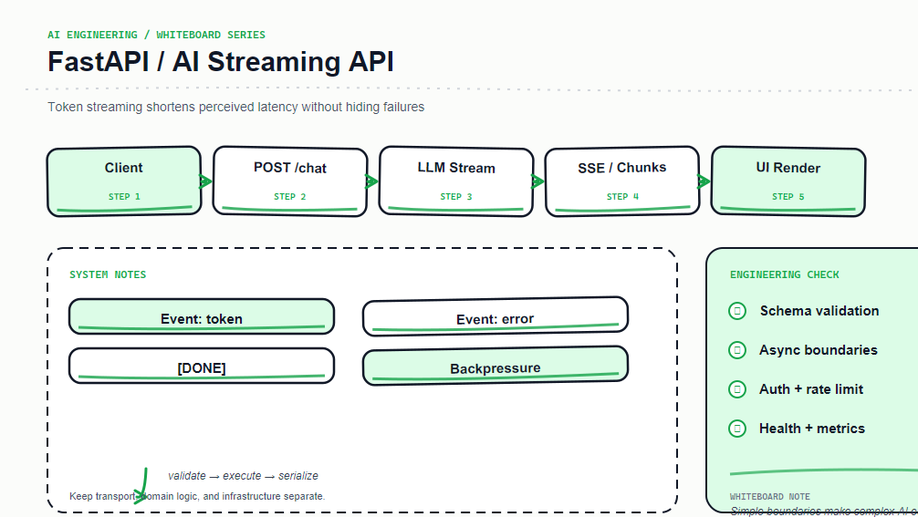
Build cancellable and observable AI streaming endpoints with generators, SSE framing, and disconnect handling.
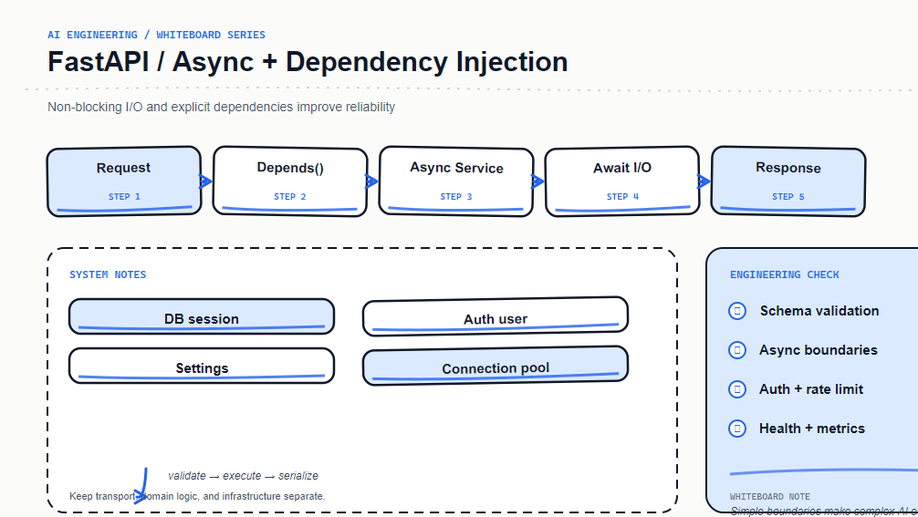
Understand async/sync boundaries, pool lifecycles, dependency scopes, and concurrency control in FastAPI.
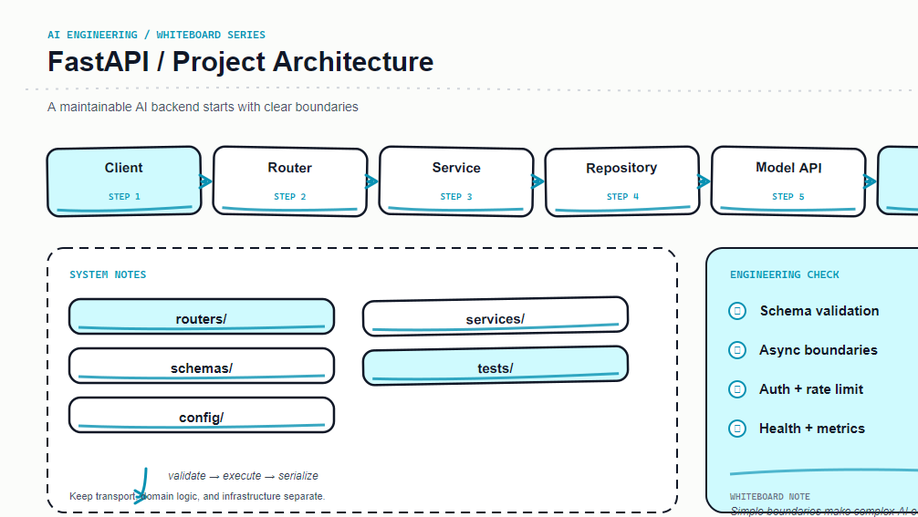
Organize a FastAPI service with layers, dependency injection, and configuration so AI endpoints stay testable and deployable.
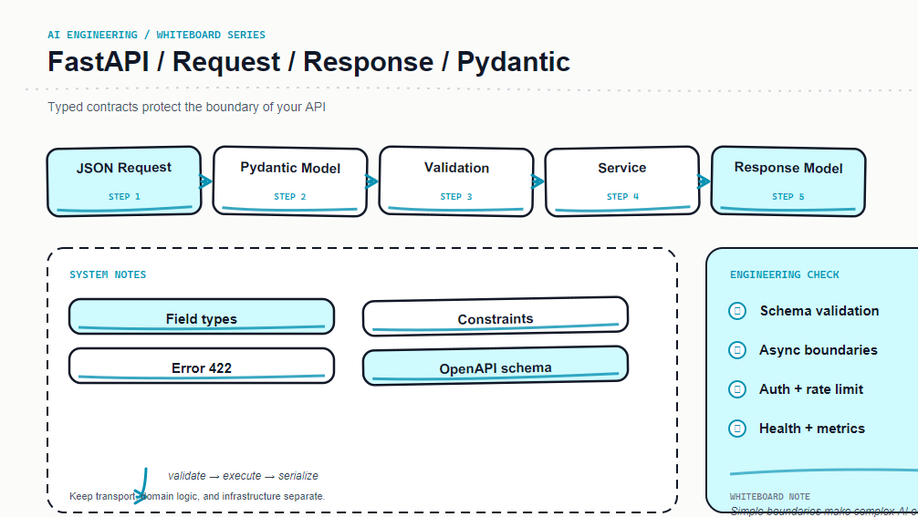
Use Pydantic schemas, field validation, response shaping, and consistent errors instead of fragile dictionary conventions.
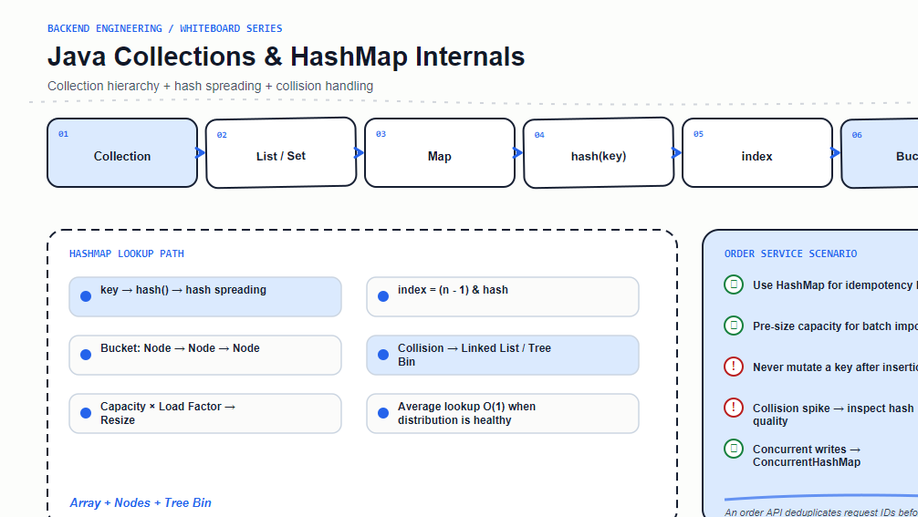
A scenario-driven guide to Java Collections & HashMap Internals, including boundaries, failure paths, and production trade-offs.
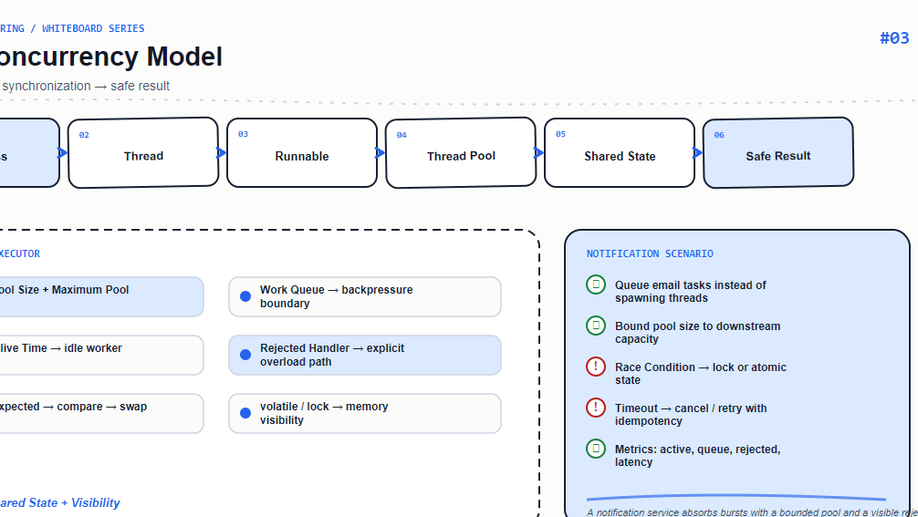
A scenario-driven guide to Java Concurrency Model, including boundaries, failure paths, and production trade-offs.
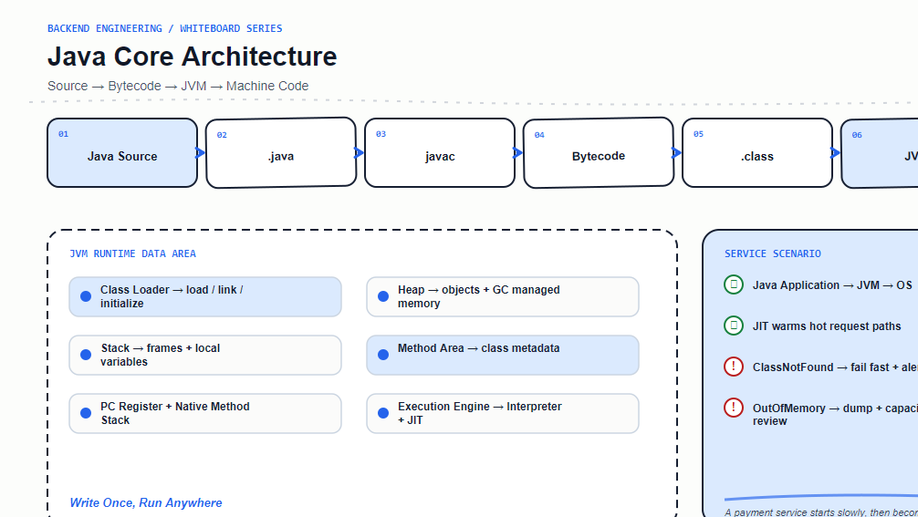
A scenario-driven guide to Java Core Architecture, including boundaries, failure paths, and production trade-offs.
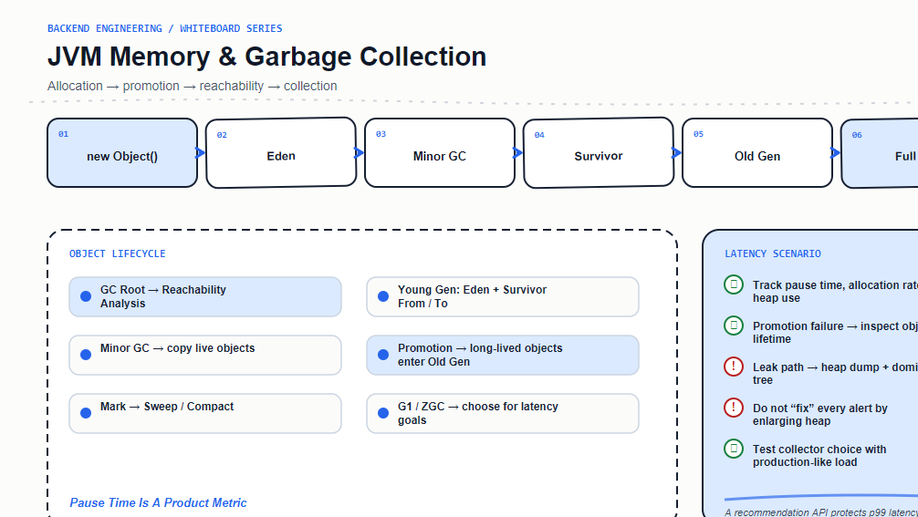
A scenario-driven guide to JVM Memory & Garbage Collection, including boundaries, failure paths, and production trade-offs.
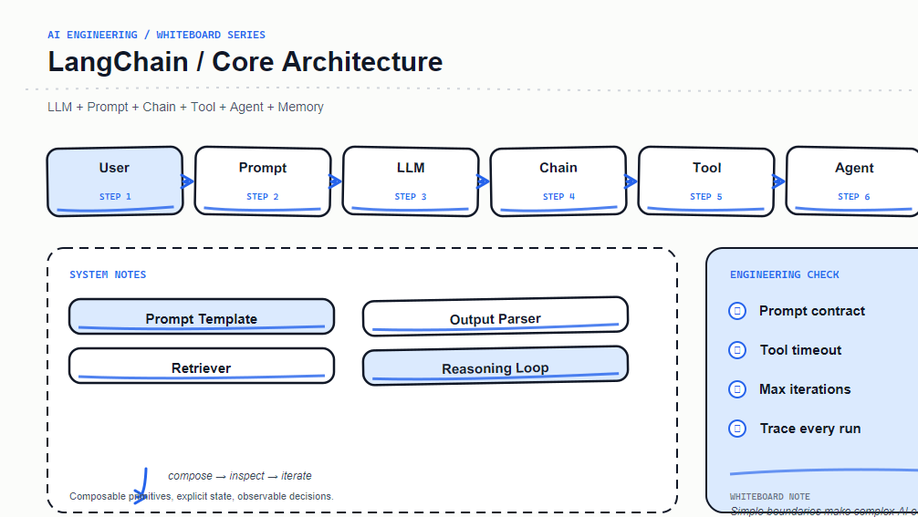
Understand how LangChain composes prompts, models, parsers, and Runnable stages into testable AI workflows.
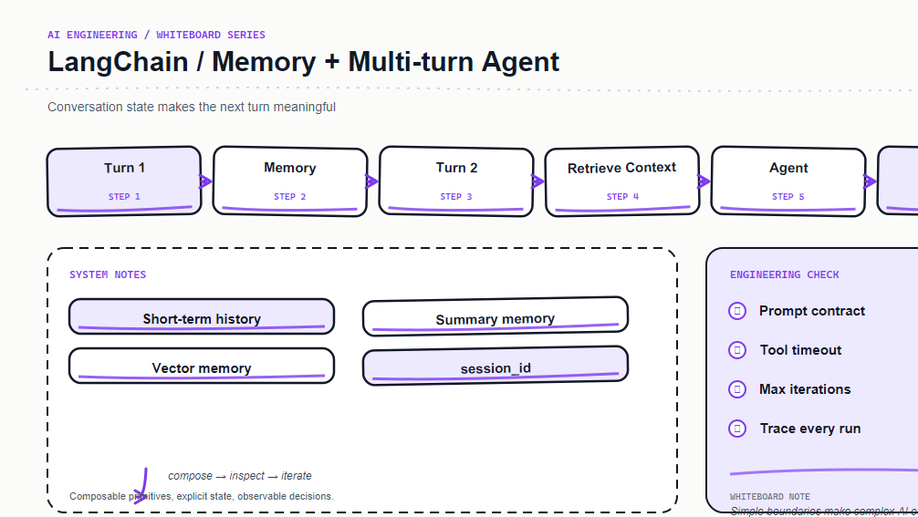
Design conversation history, summary memory, and long-term memory with clear state, capacity, and privacy boundaries.
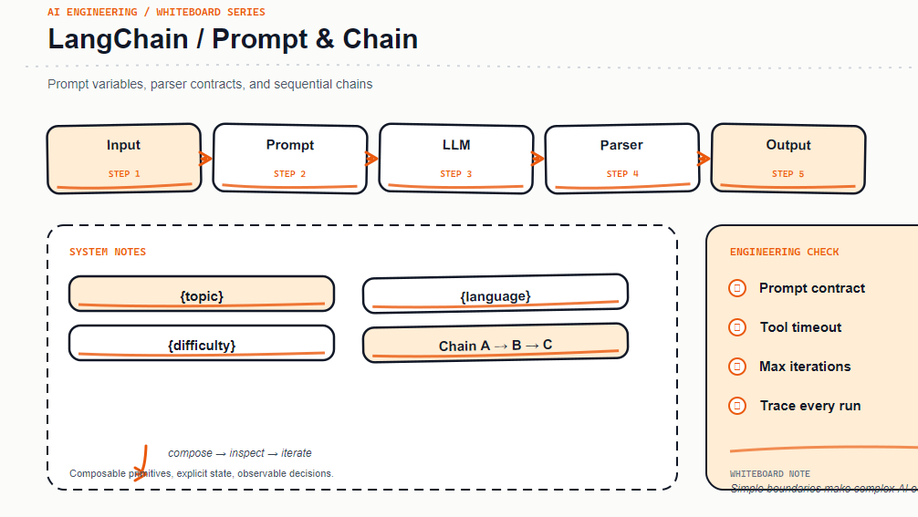
Use templates, variable contracts, message roles, and composition to build versioned and evaluable prompt chains.
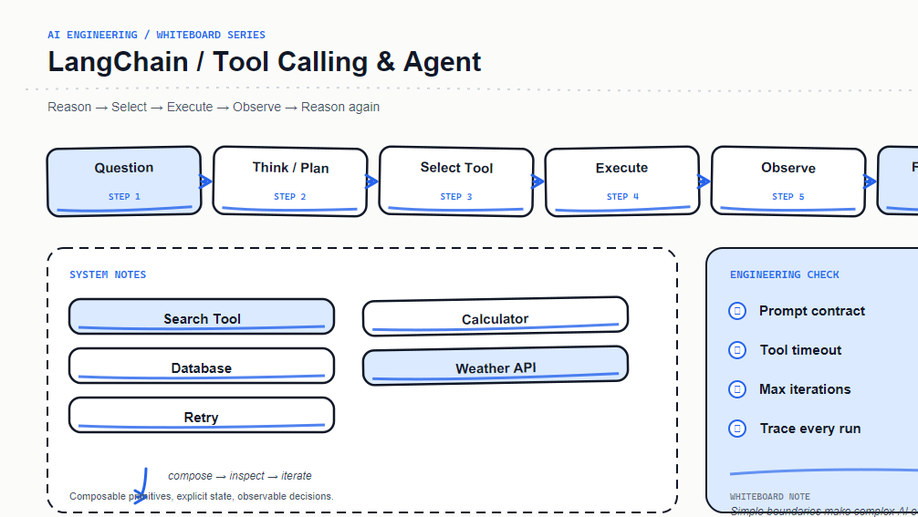
Design controllable agents with explicit tool schemas, decision loops, execution boundaries, and error recovery.
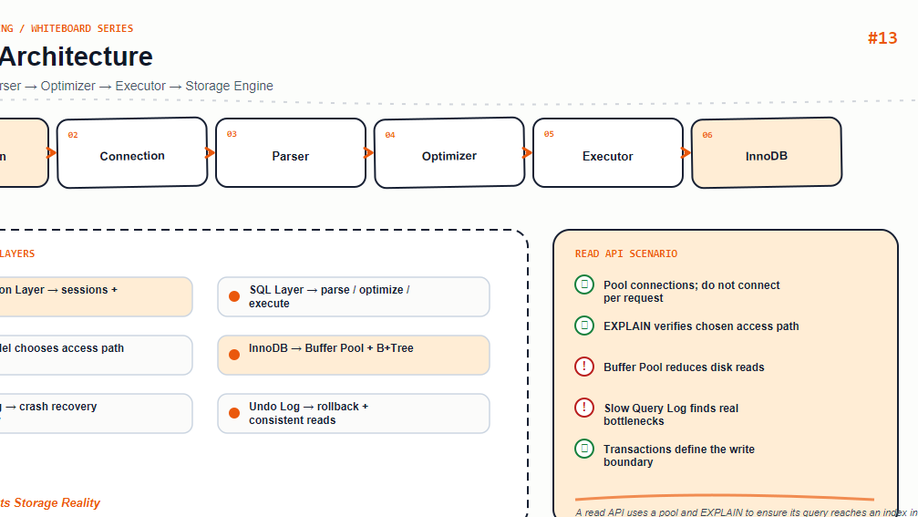
A scenario-driven guide to MySQL Architecture, including boundaries, failure paths, and production trade-offs.
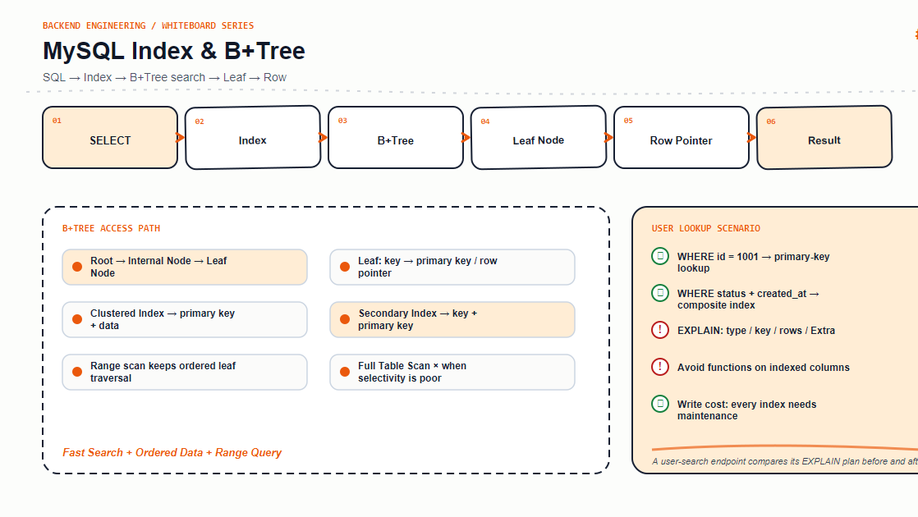
A scenario-driven guide to MySQL Index & B+Tree, including boundaries, failure paths, and production trade-offs.
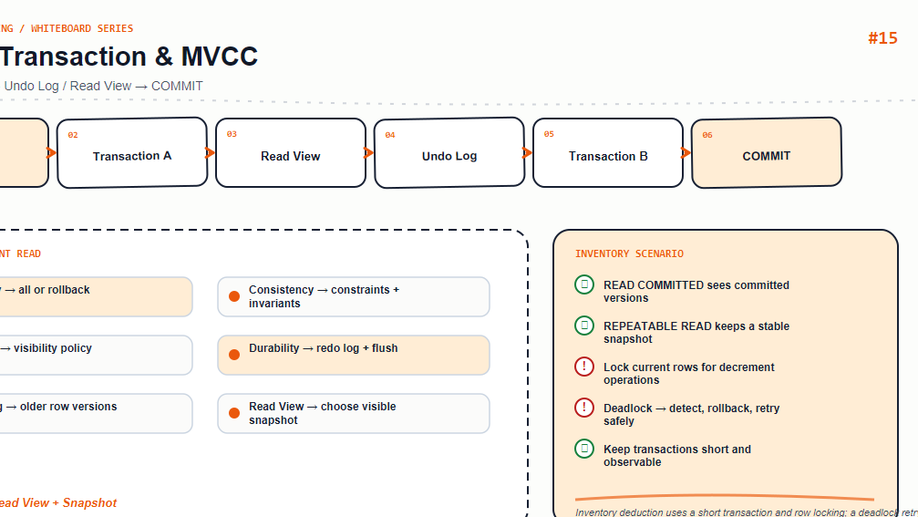
A scenario-driven guide to MySQL Transaction & MVCC, including boundaries, failure paths, and production trade-offs.
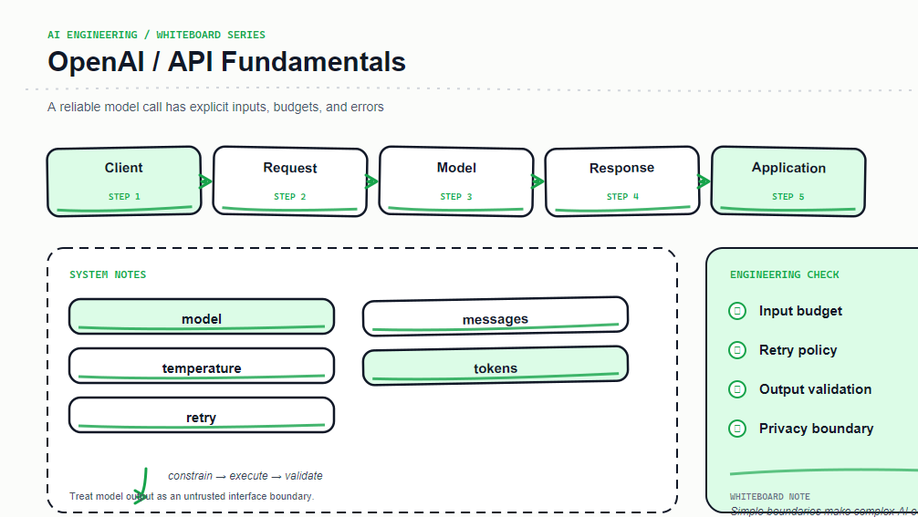
Build a reliable model API foundation with client setup, message structure, timeouts, retries, and cost controls.
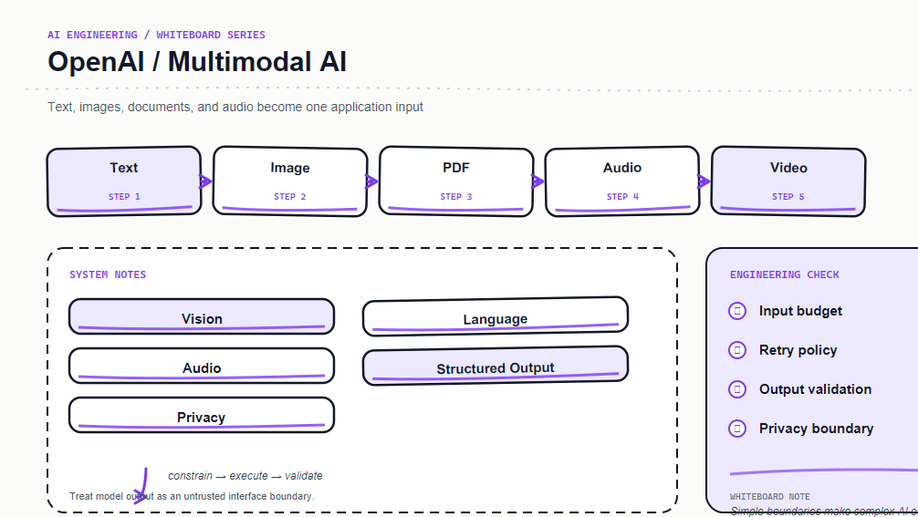
Design multimodal input pipelines with preprocessing, cost, privacy, and structured output for images and documents.
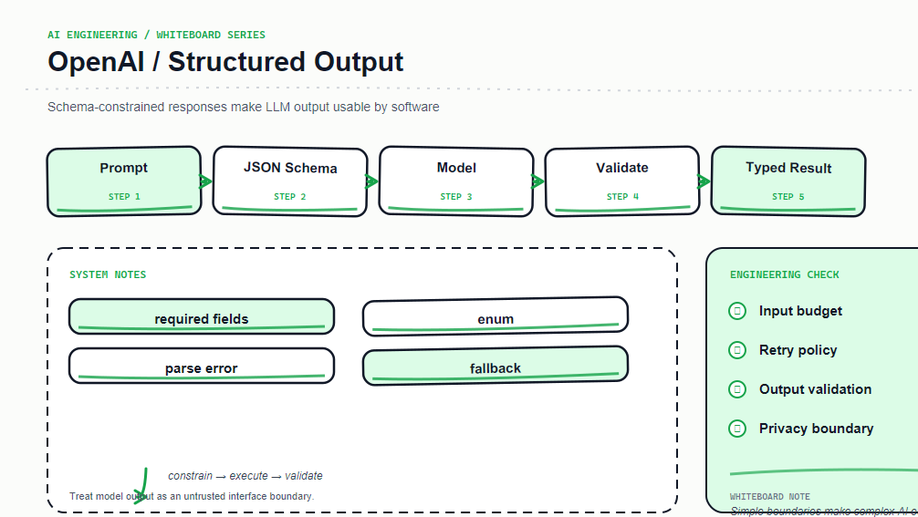
Constrain model output with JSON Schema and Pydantic while handling refusals, parse failures, and schema evolution.
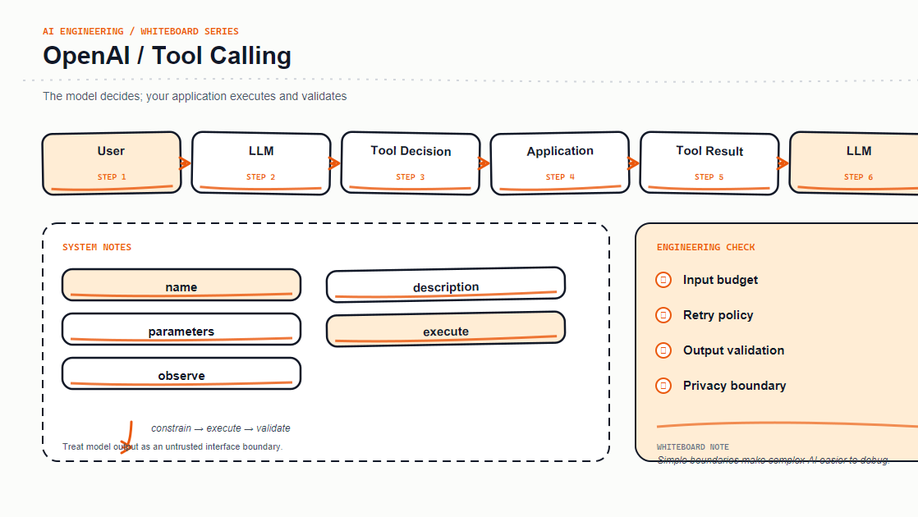
Build auditable function-calling loops with explicit schemas, model decisions, application execution, and result handoff.
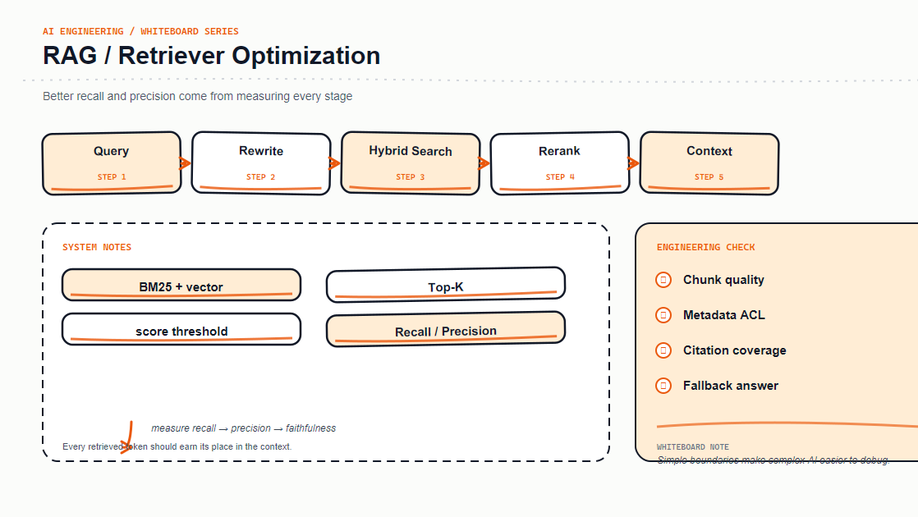
Tune RAG retrievers with BM25, vector search, hybrid recall, reranking, and context compression trade-offs.
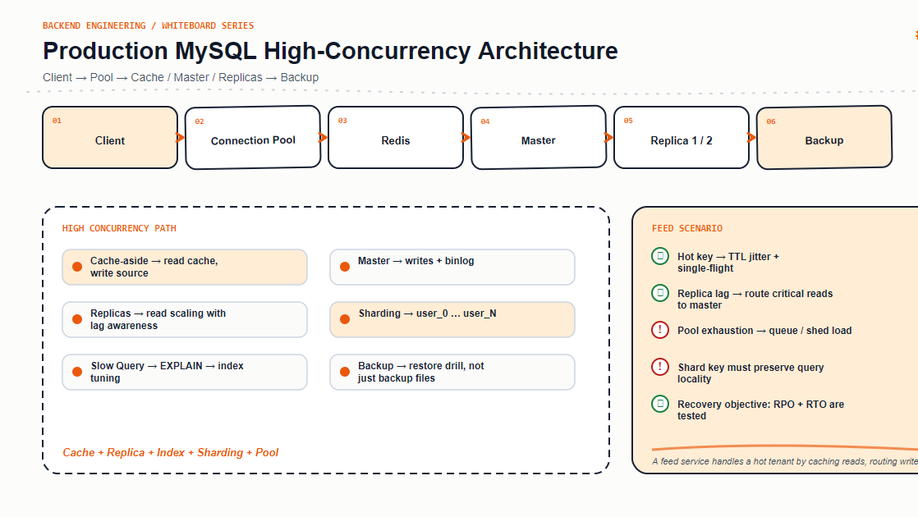
A scenario-driven guide to Production MySQL High-Concurrency Architecture, including boundaries, failure paths, and production trade-offs.
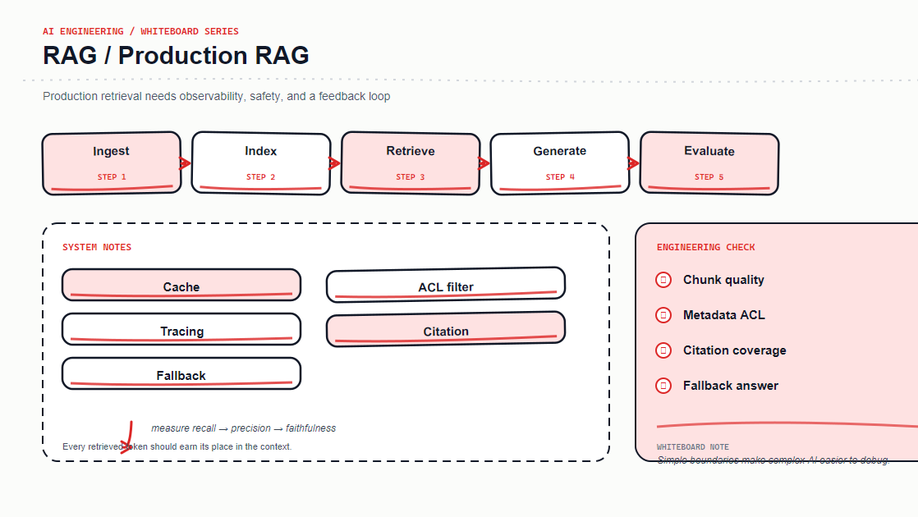
Design deployable RAG systems with ingestion, permission filters, index versions, caching, evaluation, and graceful degradation.
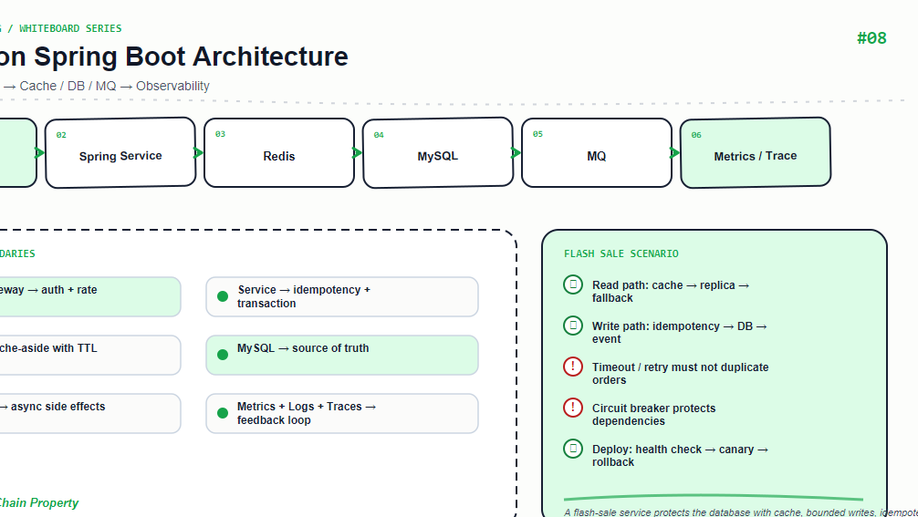
A scenario-driven guide to Production Spring Boot Architecture, including boundaries, failure paths, and production trade-offs.
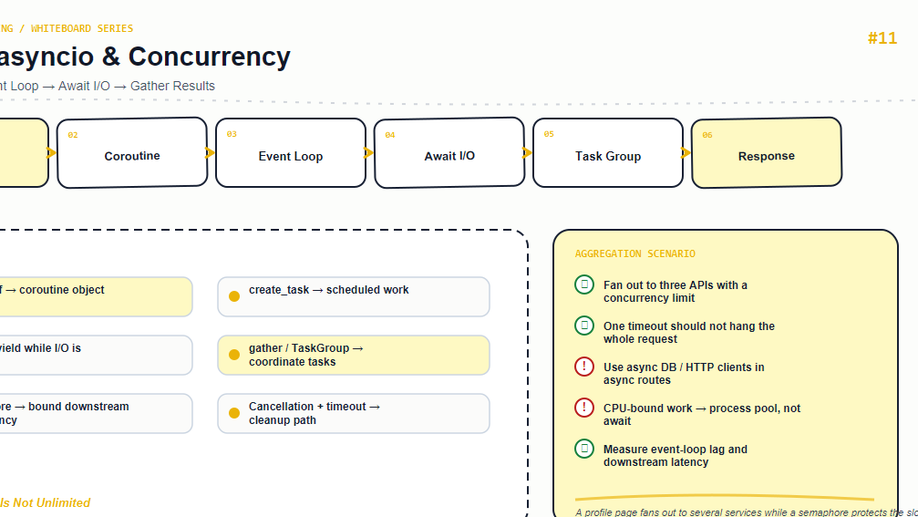
A scenario-driven guide to Python asyncio & Concurrency, including boundaries, failure paths, and production trade-offs.
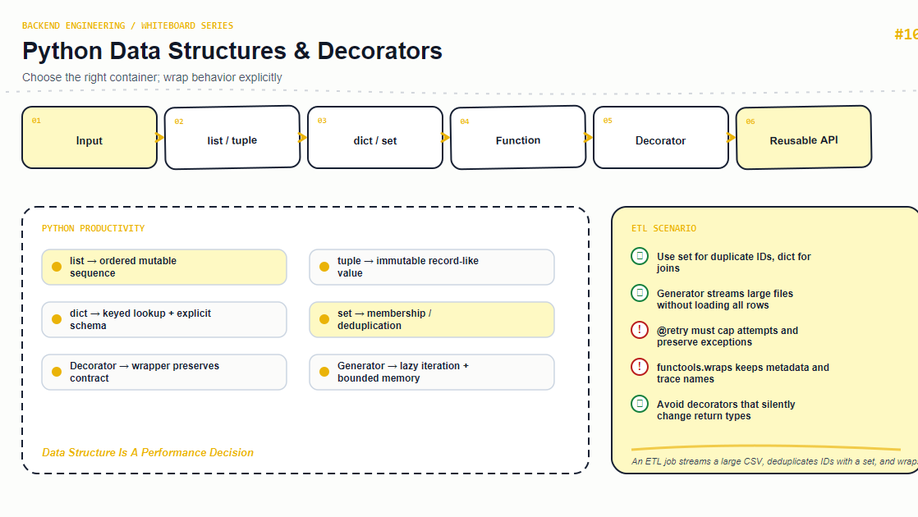
A scenario-driven guide to Python Data Structures & Decorators, including boundaries, failure paths, and production trade-offs.
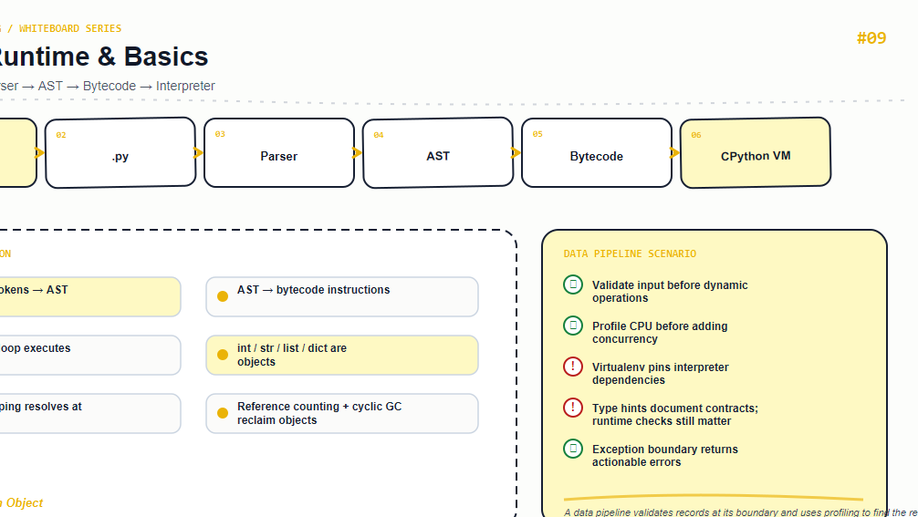
A scenario-driven guide to Python Runtime & Basics, including boundaries, failure paths, and production trade-offs.
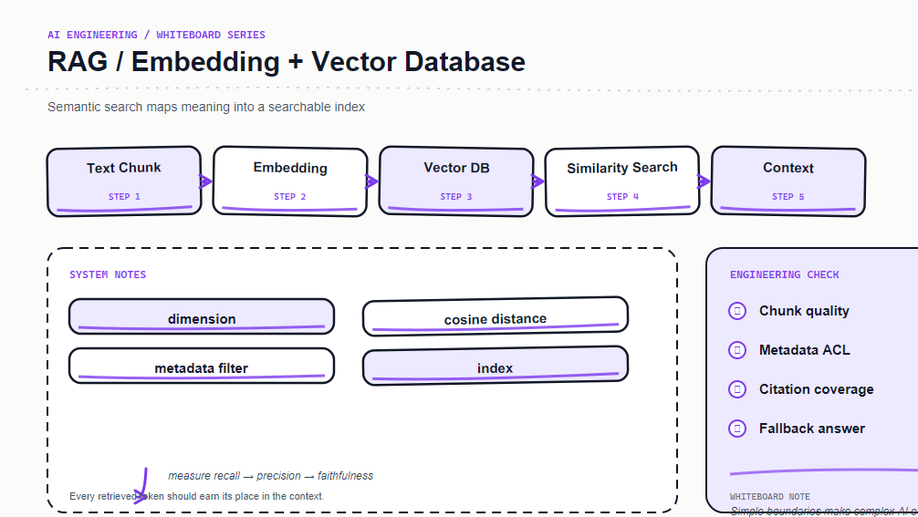
Understand embeddings, distance metrics, metadata, indexing, and incremental updates for reliable vector retrieval.
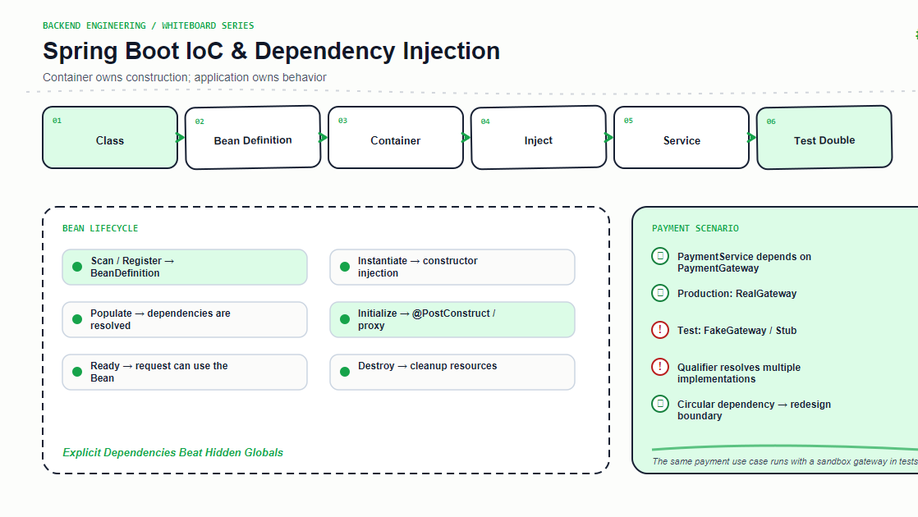
A scenario-driven guide to Spring Boot IoC & Dependency Injection, including boundaries, failure paths, and production trade-offs.
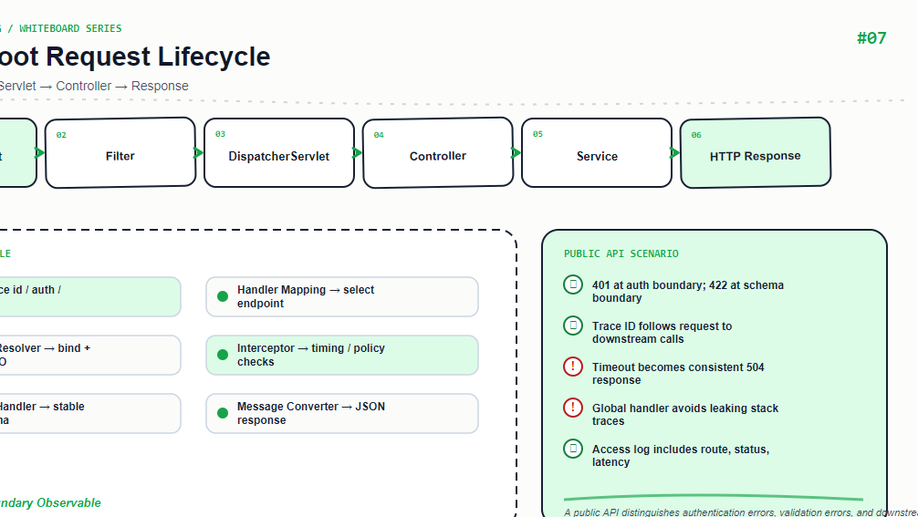
A scenario-driven guide to Spring Boot Request Lifecycle, including boundaries, failure paths, and production trade-offs.
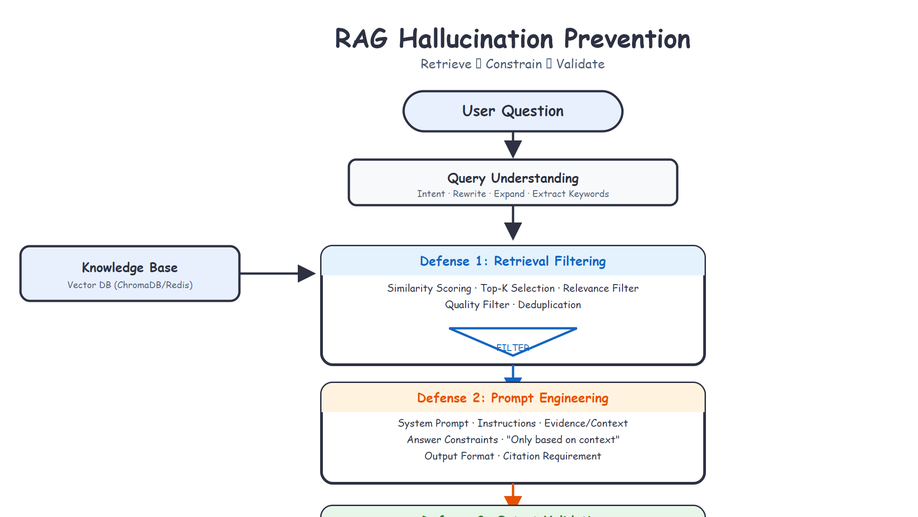
Learn how to prevent LLM hallucinations in RAG systems with a three-layer approach: retrieval filtering, prompt engineering, and output validation
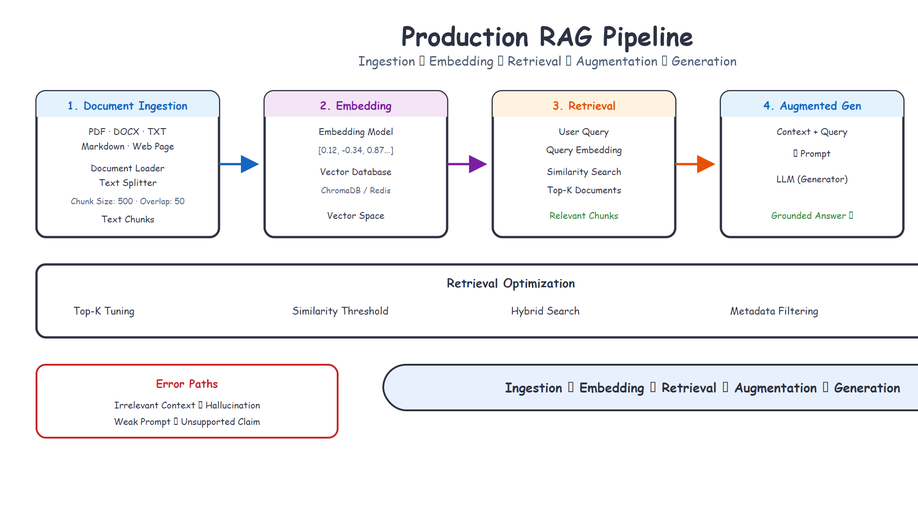
A comprehensive guide to building a production-ready RAG (Retrieval-Augmented Generation) pipeline using LangChain, covering document preprocessing, vector storage, and retrieval optimization
No articles found for this filter. Try another tag.