RAG Embeddings and Vector Databases: The Engineering Behind Similarity

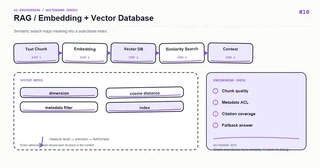
Whiteboard: RAG — RAG Embeddings and Vector Databases.
A vector database does not understand your business automatically. It efficiently finds neighbors in a chosen vector space. The engineering questions are embedding versions, distance metrics, filters, and consistency.
Core mental model
Documents and queries need compatible embedding models and preprocessing. Index records should include embedding_model, dimensions, and corpus_version for rebuilds and rollback.
Key mechanics
Apply metadata filters before or as part of vector search so different tenants, languages, and permission scopes never share the candidate set.
Python example
from uuid import uuid4

record = {
    "id": str(uuid4()),
    "text": "A refund request needs an order id and a reason.",
    "vector": embed("A refund request needs an order id and a reason."),
    "metadata": {"tenant_id": "acme", "language": "en", "embedding_model": "text-embedding-3-small", "corpus_version": "2026-08-21"},
}
# Similarity is never an authorization check.
Course focus
This article turns the whiteboard into explicit engineering boundaries: define inputs and outputs first, then decide how state, failures, and observability work. The examples use Python and focus on durable design principles rather than a particular provider version; verify APIs against the documentation for your installed dependencies.
Engineering practice
- Keep business rules in the application layer instead of hiding them in untestable prompts or route handlers.
- Add timeouts, bounded retries, and idempotency keys to external calls; retries are not a complete error strategy.
- Record a request id, latency, input version, model/index version, and outcome without logging sensitive raw content.
- Use a small fixed regression set first, then monitor quality and cost with sampled production traffic.
Common mistakes
- Drawing only the happy path and omitting timeouts, empty results, rate limits, and rollback paths.
- Letting one function parse input, call providers, build prompts, and persist data.
- Replacing typed contracts with string conventions that can only be verified by manual integration.
Production checklist
- Inputs, outputs, and error responses have explicit schemas
- External dependencies have timeouts, bounded retries, rate limits, and fallbacks
- Logs, metrics, and traces can be correlated to one request
- Critical paths have unit tests, integration tests, and offline evaluation samples
- Secrets, user content, and provider responses follow least-privilege and privacy rules
Practice
Implement the smallest loop shown on the whiteboard. Inject a timeout, an empty result, and a malformed payload, then check whether the system remains stable and diagnosable. Add one metric that proves your optimization improved quality or latency.
Hands-on exercise
Build two embedding versions from the same corpus. Record dimensions, index size, Top-K overlap, and Recall@K before deciding whether to switch.
Conclusion
An AI feature becomes maintainable when every arrow on the whiteboard maps to an input, an output, and a failure strategy.
